Turn Your Media Storage Into an Intelligent Archive
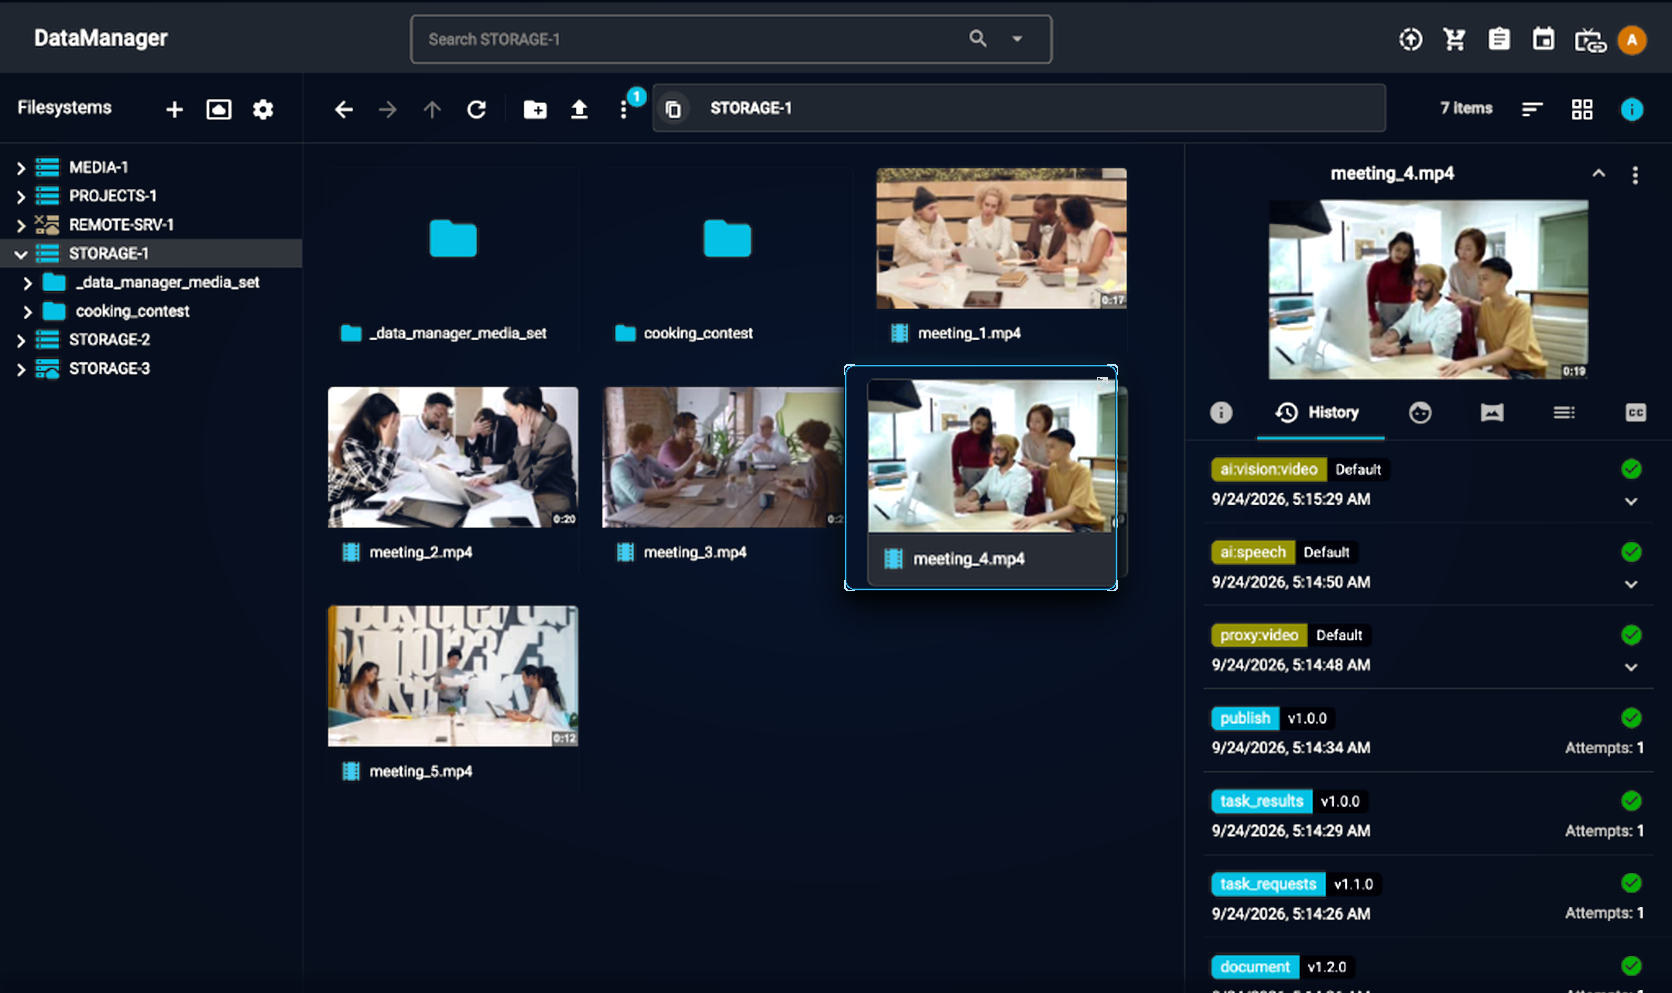
Search speech, faces, and visuals across your existing SAN, NAS, and S3 in under 1.2s. Zero file migration. Zero cloud egress. $0 token taxes.
Zero Cloud Token Fees
GPU-accelerated LLM and media AI run locally on the edge—no per-minute transcription fees, cloud token overages, or bandwidth taxes.
Inter-Storage Management
Directly mounts and indexes existing SAN/NAS (SMB, NFS), AWS S3 object stores, and LTO tape archives in place—no drive reformatting.
Live Semantic Discovery Sandbox
Ask in plain language from the browser. DataManager AI understands meaning—not just filenames:
DataManager AI Application
One catalog for all your storage. DataManager AI connects your SAN, NAS, cloud buckets, and tape archives into a single web console and native NLE panel—so editors find and cut footage in seconds without copying files.

Existing Storage Silos
Direct in-place indexing over your active SAN, NAS, S3 buckets, and LTO tape without moving a single file.
DataManager AI Engine
100% on-premises GPU compute for semantic search, speech-to-text, visual tagging, and catalog unification.
AI Agent Panels
Instant timeline access inside Adobe Premiere and Blackmagic DaVinci Resolve, alongside universal web console access.
Existing Storage Silos
DataManager AI mounts directly over your existing storage—indexing active SAN/NAS (SMB, NFS, NVMe-oF file shares), cloud object storage (AWS S3, Wasabi), and cold LTO tape in place with zero data migration or drive reformatting. Shelved tape archives remain instantly searchable via lightweight proxy caches without unspooling physical media.
What Teams Use Every Day
From browser-based semantic search to native timeline drop-ins inside Adobe Premiere and Blackmagic DaVinci Resolve.
Native Adobe Premiere Extension Panel
Editors never leave their Adobe Premiere sequence. Search natural language dialogue or visual scenes across your entire on-prem SAN/NAS repository and drop matching cuts directly onto the timeline with frame-accurate in/out points in <1.2 seconds.
Zero-Touch Ingest & Local GPU Transcoding
As soon as camera volumes or remote field drops mount, DataManager AI immediately begins generating lightweight editing proxies at up to 10x real-time speed on local GPUs. Smart block-level deduplication identifies duplicate takes before consuming expensive Tier-1 flash capacity.
Enterprise Impact & Media Intelligence
Explore how DataManager AI delivers high-performance architecture across executive leadership, local GPU intelligence engines, and distributed studio workflows.
Zero Workflow Disruption & Rapid Turnaround
Eliminate delivery bottlenecks. Incoming camera cards, field drones, and multi-suite timelines automatically index and generate scrubbable proxies instantly, cutting delivery cycles without reformatting legacy drives.
Air-Gapped Isolation & Strict Data Sovereignty
100% on-premises GPU model weights and speech/vision embeddings. Zero external cloud telemetry and zero third-party API exposure. Proprietary footage stays entirely behind facility firewalls.
Zero Context Switching Inside Timeline Panels
Never leave the cut. Native Adobe Premiere and Blackmagic DaVinci Resolve panels let editors search spoken words, visual scenes, and faces—previewing waveforms and dragging clips straight onto the active sequence playhead in <1.2s.
$0 Token Taxes & Eliminating Egress Tolls
Eliminate unpredictable recurring SaaS line items and cloud indexing fees. Unlimited speech-to-text, facial recognition, and vector queries run on local hardware with predictable CapEx/OpEx and zero per-minute billing.
Flexible Deployment Options
Choose how you want to run Apace intelligence across your facility. Whether deploying a turnkey GPU storage appliance or integrating headless AI microservices via REST API.
On-Premises GPU vs Cloud MAM Cost Delta
Simulate your monthly footage volume to see how Apace’s fixed on-prem GPU inference eliminates recurring per-minute indexing fees and cloud egress tolls.
DataManager AI + gStor
An all-in-one, rack-ready appliance combining high-speed NVMe/hybrid shared storage with dedicated NVIDIA GPU acceleration and unified MAM. Consolidates multi-tier storage silos, automates NLE workflows, and runs local LLM semantic search with $0 cloud token taxes.
AI Only as an API
A headless, containerized AI engine exposing RESTful endpoints and WebSockets. Seamlessly embeds localized facial recognition, speech-to-text, OCR, and vector embeddings into third-party MAMs and custom pipelines.
Architecture & Feature Comparison
Compare technical capabilities, hardware dependencies, and integration scope across both models.
| Feature / Model | DataManager AI + gStor | AI Only as an API |
|---|---|---|
| Delivery Method | Turnkey Hardware Appliance | Docker / K8s Microservices |
| Unified Multi-Storage Catalog | check Yes + Local Shared Pool | BYO Storage |
| Adobe Premiere & Blackmagic DaVinci Resolve Panels | check Included | Custom API Integration |
| Localized GPU Vision & LLM AI | check Built-in Dedicated GPU | check Dedicated API Endpoints |
| Recurring Cloud Token Fees | $0.00 (100% Local) | $0.00 (Self-Hosted) |
| RESTful & Webhook API | Full Stack Management API | check Native AI API Engine |
| Included Hardware | gStor Enterprise Enclosure | BYO GPU Nodes / Cluster |
| Primary User Persona | Post Supervisors, Editors, Facility Engineers & Broadcast Ops | Developers & System Integrators |